RandomShapeletTransform
- class RandomShapeletTransform(n_shapelet_samples: int = 10000, max_shapelets: int | None = None, min_shapelet_length: int = 3, max_shapelet_length: int | None = None, remove_self_similar: bool = True, batch_size: int = 100, verbose: int = 0, time_limit_in_minutes: float = 0.0, contract_max_n_shapelet_samples: float = inf, n_jobs: int = 1, parallel_backend=None, random_state: int | None = None)[source]
Bases:
BaseCollectionTransformerRandom Shapelet Transform.
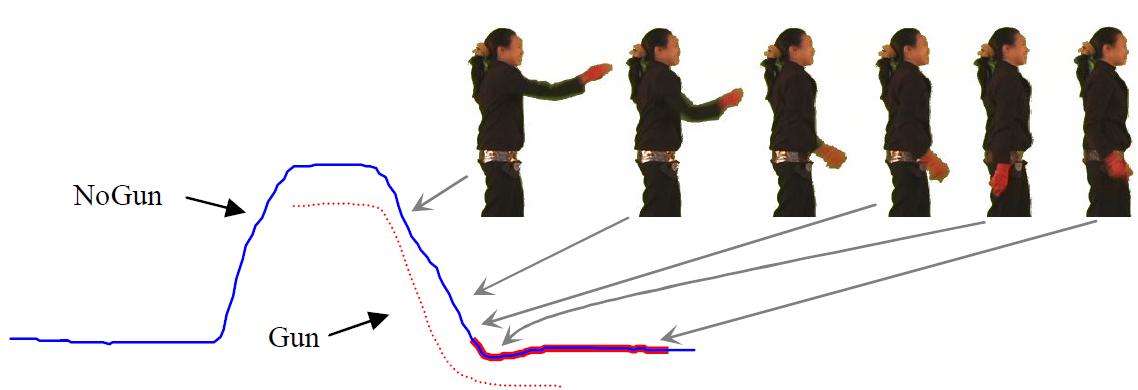
Implementation of the binary shapelet transform along the lines of [1], [2], with randomly extracted shapelets. A shapelet is a subsequence from the training set. The transform finds a set of shapelets that are good at separating the classes based on the distances between shapelets and whole series. The distance between a shapelet and a series (called sDist in the literature) is the minimum mean squared distance between the z-normalised shapelet and every z-normalised window of the same length in the series.
Given
nseries withdchannels, candidate shapelets are extracted and filtered in batches.For each candidate shapelet:
Extract a shapelet from an instance with random length, position and channel.
Z-normalise the shapelet.
Find the distance from the shapelet to all training cases.
Derive a binary orderline and score the shapelet by information gain.
Retain only the best shapelets per class.
- Parameters:
- n_shapelet_samplesint, default=10000
Number of candidate shapelets to assess. Ignored when
time_limit_in_minutes > 0.- max_shapeletsint or None, default=None
Maximum number of shapelets to keep. The shapelet budget is divided equally among the classes. If None, set to
min(10 * n_cases, 1000)during fit.- min_shapelet_lengthint, default=3
Lower bound on candidate shapelet lengths.
- max_shapelet_lengthint or None, default=None
Upper bound on candidate shapelet lengths. If None, the length of the longest input series is used. A candidate is also limited by the length of its source series.
- remove_self_similarbool, default=True
Remove overlapping “self-similar” shapelets when merging candidate shapelets.
- batch_sizeint, default=100
Number of shapelet candidates processed before being merged into the set of best shapelets.
- verboseint, default=0
Level of output printed during fit. Level 1 reports the fit configuration, periodic progress and a final summary. Level 2 and above additionally report every candidate batch and estimated remaining time.
- time_limit_in_minutesfloat, default=0.0
Time contract to limit build time in minutes, overriding n_shapelet_samples. The default of 0 means
n_shapelet_samplesis used.- contract_max_n_shapelet_samplesfloat, default=np.inf
Maximum number of shapelets to extract when
time_limit_in_minutesis set.- n_jobsint, default=1
The number of jobs to run in parallel for both
fitandtransform.-1means using all processors.- parallel_backendstr, ParallelBackendBase instance or None, default=None
Joblib parallelisation backend. If None,
prefer="threads"is used. Valid options include"loky","multiprocessing","threading", or a custom backend. See the JoblibParalleldocumentation for details.- random_stateint or None, default=None
Seed for random number generation.
- Attributes:
- n_classes_int
The number of classes.
- n_cases_int
The number of training cases.
- n_channels_int
The number of channels per case.
- max_n_timepoints_int
The maximum series length in the training data.
- classes_np.ndarray
The class labels.
- shapeletslist of tuple
The stored shapelets after fitting. Each tuple has a fixed layout
(quality, length, position, channel, case_index, class_index, distance_index, values):class_indexindexesclasses_,distance_indexis reserved for fitting and reset to-1in fitted records, andvaluesis the z-normalised subsequence from the source case. The layout matches the numeric working records used during fitting, which populate every field exceptvalues.
See also
ShapeletTransformClassifier
Notes
Capabilities ¶ Missing Values
No
Multithreading
Yes
Inverse Transform
No
Univariate
Yes
Multivariate
Yes
Unequal Length
Yes
For the Java version, see TSML.
References
[1]Jon Hills et al., “Classification of time series by shapelet transformation”, Data Mining and Knowledge Discovery, 28(4), 851-881, 2014.
[2]A. Bostrom and A. Bagnall, “Binary Shapelet Transform for Multiclass Time Series Classification”, Transactions on Large-Scale Data and Knowledge-Centered Systems, 32, 2017.
Methods
clone([random_state])Obtain a clone of the object with the same hyperparameters.
fit(X[, y])Fit transformer to X, optionally using y if supervised.
fit_transform(X[, y])Fit to data, then transform it.
get_class_tag(tag_name[, raise_error, ...])Get tag value from estimator class (only class tags).
Get class tags from estimator class and all its parent classes.
get_fitted_params([deep])Get fitted parameters.
get_params([deep])Get parameters for this estimator.
get_tag(tag_name[, raise_error, ...])Get tag value from estimator class.
get_tags()Get tags from estimator.
reset([keep])Reset the object to a clean post-init state.
set_params(**params)Set the parameters of this estimator.
set_tags(**tag_dict)Set dynamic tags to given values.
transform(X[, y])Transform X and return a transformed version.
- clone(random_state=None)[source]
Obtain a clone of the object with the same hyperparameters.
A clone is a different object without shared references, in post-init state. This function is equivalent to returning
sklearn.cloneofself. Equal in value totype(self)(**self.get_params(deep=False)).- Parameters:
- random_stateint, RandomState instance, or None, default=None
Sets the random state of the clone. If
None, the random state is not set. Ifint,random_stateis the seed used by the random number generator. IfRandomStateinstance,random_stateis the random number generator.
- Returns:
- estimatorobject
Instance of
type(self), clone of self (see above)
- fit(X, y=None)[source]
Fit transformer to X, optionally using y if supervised.
Writes to self: - is_fitted : flag is set to True. - model attributes (ending in “_”) : dependent on estimator
- Parameters:
- Xnp.ndarray or list
Data to fit transform to, of valid collection type. Input data, any number of channels, equal length series of shape
(
n_cases, n_channels, n_timepoints)
or list of numpy arrays (number of channels, series length) of shape[n_cases], 2D np.array(n_channels, n_timepoints_i), wheren_timepoints_iis length of seriesi. Other types are allowed and converted into one of the above.Different estimators have different capabilities to handle different types of input. If
self.get_tag("capability:multivariate")is False, they cannot handle multivariate series. Ifself.get_tag( "capability:unequal_length")is False, they cannot handle unequal length input. In both situations, aValueErroris raised if X has a characteristic that the estimator does not have the capability to handle.- ynp.ndarray, default=None
1D np.array of float or str, of shape
(n_cases)- class labels (ground truth) for fitting indices corresponding to instance indices in X. If None, no labels are used in fitting.
- Returns:
- selfa fitted instance of the estimator
- fit_transform(X, y=None)[source]
Fit to data, then transform it.
Fits the transformer to X and y and returns a transformed version of X.
- State change:
Changes state to “fitted”.
Writes to self: _is_fitted : flag is set to True. model attributes (ending in “_”) : dependent on estimator.
- Parameters:
- Xnp.ndarray or list
Data to fit transform to, of valid collection type. Input data, any number of channels, equal length series of shape
(
n_cases, n_channels, n_timepoints)
or list of numpy arrays (number of channels, series length) of shape[n_cases], 2D np.array(n_channels, n_timepoints_i), wheren_timepoints_iis length of seriesi. Other types are allowed and converted into one of the above.Different estimators have different capabilities to handle different types of input. If
self.get_tag("capability:multivariate")is False, they cannot handle multivariate series. Ifself.get_tag( "capability:unequal_length")is False, they cannot handle unequal length input. In both situations, aValueErroris raised if X has a characteristic that the estimator does not have the capability to handle.- ynp.ndarray, default=None
1D np.array of float or str, of shape
(n_cases)- class labels (ground truth) for fitting indices corresponding to instance indices in X. If None, no labels are used in fitting.
- Returns:
- transformed version of X
- classmethod get_class_tag(tag_name, raise_error=True, tag_value_default=None)[source]
Get tag value from estimator class (only class tags).
- Parameters:
- tag_namestr
Name of tag value.
- raise_errorbool, default=True
Whether a
ValueErroris raised when the tag is not found.- tag_value_defaultany type, default=None
Default/fallback value if tag is not found and error is not raised.
- Returns:
- tag_value
Value of the
tag_nametag in cls. If not found, returns an error ifraise_errorisTrue, otherwise it returnstag_value_default.
- Raises:
- ValueError
if
raise_errorisTrueandtag_nameis not inself.get_tags().keys()
Examples
>>> from aeon.classification import DummyClassifier
>>> DummyClassifier.get_class_tag("capability:multivariate")
True
- classmethod get_class_tags()[source]
Get class tags from estimator class and all its parent classes.
- Returns:
- collected_tagsdict
Dictionary of tag name and tag value pairs. Collected from
_tagsclass attribute via nested inheritance. These are not overridden by dynamic tags set byset_tagsor class__init__calls.
- get_fitted_params(deep=True)[source]
Get fitted parameters.
- State required:
Requires state to be “fitted”.
- Parameters:
- deepbool, default=True
If
True, will return the fitted parameters for this estimator and contained subobjects that are estimators.
- Returns:
- fitted_paramsdict
Fitted parameter names mapped to their values.
- get_params(deep=True)
Get parameters for this estimator.
- Parameters:
- deepbool, default=True
If True, will return the parameters for this estimator and contained subobjects that are estimators.
- Returns:
- paramsdict
Parameter names mapped to their values.
- get_tag(tag_name, raise_error=True, tag_value_default=None)[source]
Get tag value from estimator class.
Includes dynamic and overridden tags.
- Parameters:
- tag_namestr
Name of tag to be retrieved.
- raise_errorbool, default=True
Whether a
ValueErroris raised when the tag is not found.- tag_value_defaultany type, default=None
Default/fallback value if tag is not found and error is not raised.
- Returns:
- tag_value
Value of the
tag_nametag in self. If not found, returns an error ifraise_errorisTrue, otherwise it returnstag_value_default.
- Raises:
- ValueError
if raise_error is
Trueandtag_nameis not inself.get_tags().keys()
Examples
>>> from aeon.classification import DummyClassifier
>>> d = DummyClassifier()
>>> d.get_tag("capability:multivariate")
True
- get_tags()[source]
Get tags from estimator.
Includes dynamic and overridden tags.
- Returns:
- collected_tagsdict
Dictionary of tag name and tag value pairs. Collected from
_tagsclass attribute via nested inheritance and then any overridden and new tags from__init__orset_tags.
- reset(keep=None)[source]
Reset the object to a clean post-init state.
After a
self.reset()call,selfis equal or similar in value totype(self)(**self.get_params(deep=False)), assuming no other attributes were kept usingkeep.- Detailed behaviour:
- removes any object attributes, except:
hyper-parameters (arguments of
__init__) object attributes containing double-underscores, i.e., the string “__”
runs
__init__with current values of hyperparameters (result ofget_params)- Not affected by the reset are:
object attributes containing double-underscores class and object methods, class attributes any attributes specified in the
keepargument temporary callback context attached by scikit-learn
- Parameters:
- keepNone, str, or list of str, default=None
If
None, all attributes are removed except hyperparameters. Ifstr, only the attribute with this name is kept. Iflistofstr, only the attributes with these names are kept.
- Returns:
- selfobject
Reference to self.
- Raises:
- TypeError
If ‘keep’ is not a string or a list of strings.
- set_params(**params)
Set the parameters of this estimator.
The method works on simple estimators as well as on nested objects (such as
Pipeline). The latter have parameters of the form<component>__<parameter>so that it’s possible to update each component of a nested object.- Parameters:
- **paramsdict
Estimator parameters.
- Returns:
- selfestimator instance
Estimator instance.
- set_tags(**tag_dict)[source]
Set dynamic tags to given values.
- Parameters:
- **tag_dictdict
Dictionary of tag name and tag value pairs.
- Returns:
- selfobject
Reference to
self.
- transform(X, y=None)[source]
Transform X and return a transformed version.
- State required:
Requires state to be “fitted”.
Accesses in self: _is_fitted : must be True fitted model attributes (ending in “_”) : must be set, accessed by _transform
- Parameters:
- Xnp.ndarray or list
Data to fit transform to, of valid collection type. Input data, any number of channels, equal length series of shape
(
n_cases, n_channels, n_timepoints)
or list of numpy arrays (number of channels, series length) of shape[n_cases], 2D np.array(n_channels, n_timepoints_i), wheren_timepoints_iis length of seriesi. Other types are allowed and converted into one of the above.Different estimators have different capabilities to handle different types of input. If
self.get_tag("capability:multivariate")is False, they cannot handle multivariate series. Ifself.get_tag( "capability:unequal_length")is False, they cannot handle unequal length input. In both situations, aValueErroris raised if X has a characteristic that the estimator does not have the capability to handle.- ynp.ndarray, default=None
1D np.array of float or str, of shape
(n_cases)- class labels (ground truth) for fitting indices corresponding to instance indices in X. If None, no labels are used in fitting.
- Returns:
- transformed version of X